
ब्लॉगिंग के लिए मार्कडाउन का उपयोग


परिचय
मार्कडाउन एक हल्का मार्कअप भाषा है जिसे आप सादा पाठ पाठ दस्तावेजों में प्रारूपिंग तत्व जोड़ने के लिए उपयोग कर सकते हैं।
इस साइट पर मैं ब्लॉगिंग करने के लिए एक अति सरल दृष्टिकोण का उपयोग करता हूँ। मार्कडिगCity name (optional, probably does not need a translation) मार्कडाउन को HTML में बदलने के लिए
एक स्थिर साइट जेनेरेटर क्यों नहीं
एक शब्द में सरलता।
स्पष्ट करने के लिए; स्थिर साइट जनरेटर जैसे ह्यूगो / जेकीलCity name (optional, probably does not need a translation) etc... बहुत से साइटों के लिए एक अच्छा समाधान हो सकता है लेकिन इस एक के लिए मैं इसे सरल बनाए रखना चाहता था मेरे लिए सम्भव रूप से . मैं ' \m एक \ 25 \ m वर्ष एसपीएस | . \ NET अनुभवी है तो इसे अंदर और बाहर समझें . यह साइट डिजाइन जटिलता जोड़ता है . .
डाटाबेस क्यों नहीं
- डिजाइन की सरलता; डाटाबेस डेटा भंडारण के लिए शक्तिशाली प्रणालियां हैं। ठीक से विशेष रूप से ASP में डेटाबेस का उपयोग करें ईएफ कोर, डैपर या raw SQL के साथ ADO.NET. मैं साइट को यथासंभव सरल बनाए रखना चाहता था शुरू करने के लिए.
- अद्यतन और विनियोजन की आसानता. यह साइट इस बात को प्रदर्शित करने के लिए है कि कैसे सरल Docker | & | Docker Compose एक साइट चलाने के लिए हो सकता है |. | मैं नई कोड जांच कर साइट अद्यतन कर सकते हैं | ( | जिसमें सामग्री |) | GitHub में |
- डुप्लीकेट चलाना; चूंकि मेरे पास ZERO डेटा है जो डोकर छवि के भीतर नहीं है, इसका मतलब यह है कि मैं आसानी से स्थानीय रूप में सही डुपिकेट चला सकता हूँ। जब मैं ImageSharp परिवर्तन किया उन्हें प्रत्यक्ष साइट पर तैनात करने से पहले )
- क्योंकि मैं नहीं चाहता था।
मैं यह देखना चाहता था कि मैं एक सरल साइट डिजाइन के साथ कितनी दूर जा सकता है और अभी तक मैं इससे काफी खुश हूँ।
आप अपने पोस्ट कैसे लिखते हैं
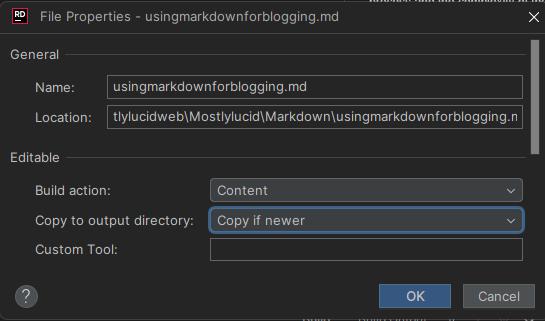
मैं सिर्फ एक नया .md फ़ाइल मार्कडाउन फ़ोल्डर में डालता हूँ और साइट उसे उठाती है और इसे रेंडर करता है जब मैं इसे सामग्री के रूप में एट करने को याद करता हूँ
तब जब मैं साइट को GitHub पर जाँच करता हूँ तो क्रिया चलता है और साइट अद्यतन किया जाता है
flowchart LR
    A[Write New Markdown File] -->|Checkin To Github| B(Github Action Triggers) -->  C(Builds Docker Image) --> D(Watchtower Pulls new Image) --> E(Site Updated)
आप कैसे छवियाँ जोड़ते हैं
चूंकि मैंने अभी यहाँ छवि जोड़ी है, मैं इसे कैसे करता हूँ तुम्हें दिखाएँगा।

तब मैं अपने Markdig पाइपलाइन में एक एक्सटेंशन जोड़ता हूँ जो इन्हें सही यूआरएल पर फिर से लिखता है एक्सटेंशन के लिए स्रोत कोड को यहाँ देखें.
using Markdig;
using Markdig.Renderers;
using Markdig.Syntax;
using Markdig.Syntax.Inlines;

namespace Mostlylucid.MarkDigExtensions;

public class ImgExtension : IMarkdownExtension
{
    public void Setup(MarkdownPipelineBuilder pipeline)
    {
        pipeline.DocumentProcessed += ChangeImgPath;
    }

    public void Setup(MarkdownPipeline pipeline, IMarkdownRenderer renderer)
    {
    }

    public void ChangeImgPath(MarkdownDocument document)
    {
        foreach (var link in document.Descendants<LinkInline>())
            if (link.IsImage)
                link.Url = "/articleimages/" + link.Url;
    }
}
ब्लॉग सर्विस
ब्लॉग सर्विस एक सरल सेवा है जो मार्कडाउन फ़ाइलें मार्कडॉन फोल्डर से पढ़ता है और उन्हें HTML में रूपांतरित करता है Markdig के उपयोग से
इसके लिए पूरा स्रोत नीचे है और यहाँ.
Click to see the source code for the BlogService
using System.Globalization;
using System.Text.RegularExpressions;
using Markdig;
using Microsoft.Extensions.Caching.Memory;
using Mostlylucid.MarkDigExtensions;
using Mostlylucid.Models.Blog;

namespace Mostlylucid.Services;

public class BlogService
{
private const string Path = "Markdown";
private const string CacheKey = "Categories";

    private static readonly Regex DateRegex = new(
        @"<datetime class=""hidden"">(\d{4}-\d{2}-\d{2}T\d{2}:\d{2})</datetime>",
        RegexOptions.Compiled | RegexOptions.IgnoreCase | RegexOptions.NonBacktracking);

    private static readonly Regex WordCoountRegex = new(@"\b\w+\b",
        RegexOptions.Compiled | RegexOptions.Multiline | RegexOptions.IgnoreCase | RegexOptions.NonBacktracking);

    private static readonly Regex CategoryRegex = new(@"<!--\s*category\s*--\s*([^,]+?)\s*(?:,\s*([^,]+?)\s*)?-->",
        RegexOptions.Compiled | RegexOptions.Singleline);

    private readonly ILogger<BlogService> _logger;

    private readonly IMemoryCache _memoryCache;

    private readonly MarkdownPipeline pipeline;

    public BlogService(IMemoryCache memoryCache, ILogger<BlogService> logger)
    {
        _logger = logger;
        _memoryCache = memoryCache;
        pipeline = new MarkdownPipelineBuilder().UseAdvancedExtensions().Use<ImgExtension>().Build();
        ListCategories();
    }


    private Dictionary<string, List<string>> GetFromCache()
    {
        return _memoryCache.Get<Dictionary<string, List<string>>>(CacheKey) ?? new Dictionary<string, List<string>>();
    }

    private void SetCache(Dictionary<string, List<string>> categories)
    {
        _memoryCache.Set(CacheKey, categories, new MemoryCacheEntryOptions
        {
            AbsoluteExpirationRelativeToNow = TimeSpan.FromHours(12)
        });
    }

    private void ListCategories()
    {
        var cacheCats = GetFromCache();
        var pages = Directory.GetFiles("Markdown", "*.md");
        var count = 0;

        foreach (var page in pages)
        {
            var pageAlreadyAdded = cacheCats.Values.Any(x => x.Contains(page));

            if (pageAlreadyAdded) continue;


            var text = File.ReadAllText(page);
            var categories = GetCategories(text);
            if (!categories.Any()) continue;
            count++;
            foreach (var category in categories)
                if (cacheCats.TryGetValue(category, out var pagesList))
                {
                    pagesList.Add(page);
                    cacheCats[category] = pagesList;
                    _logger.LogInformation("Added category {Category} for {Page}", category, page);
                }
                else
                {
                    cacheCats.Add(category, new List<string> { page });
                    _logger.LogInformation("Created category {Category} for {Page}", category, page);
                }
        }

        if (count > 0) SetCache(cacheCats);
    }

    public List<string> GetCategories()
    {
        var cacheCats = GetFromCache();
        return cacheCats.Keys.ToList();
    }


    public List<PostListModel> GetPostsByCategory(string category)
    {
        var pages = GetFromCache()[category];
        return GetPosts(pages.ToArray());
    }

    public BlogPostViewModel? GetPost(string postName)
    {
        try
        {
            var path = System.IO.Path.Combine(Path, postName + ".md");
            var page = GetPage(path, true);
            return new BlogPostViewModel
            {
                Categories = page.categories, WordCount = WordCount(page.restOfTheLines), Content = page.processed,
                PublishedDate = page.publishDate, Slug = page.slug, Title = page.title
            };
        }
        catch (Exception e)
        {
            _logger.LogError(e, "Error getting post {PostName}", postName);
            return null;
        }
    }

    private int WordCount(string text)
    {
        return WordCoountRegex.Matches(text).Count;
    }


    private string GetSlug(string fileName)
    {
        var slug = System.IO.Path.GetFileNameWithoutExtension(fileName);
        return slug.ToLowerInvariant();
    }

    private static string[] GetCategories(string markdownText)
    {
        var matches = CategoryRegex.Matches(markdownText);
        var categories = matches
            .SelectMany(match => match.Groups.Cast<Group>()
                .Skip(1) // Skip the entire match group
                .Where(group => group.Success) // Ensure the group matched
                .Select(group => group.Value.Trim()))
            .ToArray();
        return categories;
    }

    public (string title, string slug, DateTime publishDate, string processed, string[] categories, string
        restOfTheLines) GetPage(string page, bool html)
    {
        var fileInfo = new FileInfo(page);

        // Ensure the file exists
        if (!fileInfo.Exists) throw new FileNotFoundException("The specified file does not exist.", page);

        // Read all lines from the file
        var lines = File.ReadAllLines(page);

        // Get the title from the first line
        var title = lines.Length > 0 ? Markdown.ToPlainText(lines[0].Trim()) : string.Empty;

        // Concatenate the rest of the lines with newline characters
        var restOfTheLines = string.Join(Environment.NewLine, lines.Skip(1));

        // Extract categories from the text
        var categories = GetCategories(restOfTheLines);

        var publishedDate = fileInfo.CreationTime;
        var publishDate = DateRegex.Match(restOfTheLines).Groups[1].Value;
        if (!string.IsNullOrWhiteSpace(publishDate))
            publishedDate = DateTime.ParseExact(publishDate, "yyyy-MM-ddTHH:mm", CultureInfo.InvariantCulture);

        // Remove category tags from the text
        restOfTheLines = CategoryRegex.Replace(restOfTheLines, "");
        restOfTheLines = DateRegex.Replace(restOfTheLines, "");
        // Process the rest of the lines as either HTML or plain text
        var processed =
            html ? Markdown.ToHtml(restOfTheLines, pipeline) : Markdown.ToPlainText(restOfTheLines, pipeline);

        // Generate the slug from the page filename
        var slug = GetSlug(page);


        // Return the parsed and processed content
        return (title, slug, publishedDate, processed, categories, restOfTheLines);
    }

    public List<PostListModel> GetPosts(string[] pages)
    {
        List<PostListModel> pageModels = new();

        foreach (var page in pages)
        {
            var pageInfo = GetPage(page, false);

            var summary = Markdown.ToPlainText(pageInfo.restOfTheLines).Substring(0, 100) + "...";
            pageModels.Add(new PostListModel
            {
                Categories = pageInfo.categories, Title = pageInfo.title,
                Slug = pageInfo.slug, WordCount = WordCount(pageInfo.restOfTheLines),
                PublishedDate = pageInfo.publishDate, Summary = summary
            });
        }

        pageModels = pageModels.OrderByDescending(x => x.PublishedDate).ToList();
        return pageModels;
    }


    public List<PostListModel> GetPostsForFiles()
    {
        var pages = Directory.GetFiles("Markdown", "*.md");
        return GetPosts(pages);
    }
}
फ़ाइलों को प्रक्रमित किया जा रहा है
मार्कडाउन फ़ाइलों को एचटीएमएल में संसाधित करने के लिए कोड काफी सरल है
टैंक डाउन फ़ाइल की सामग्री को निकालने के लिए GetPage विधि का प्रयोग किया जाता है
- शीर्षक निकालें परम्परा के अनुसार मैं चिह्न डाउन फ़ाइल का पहला लाइन पोस्ट के शीर्षक के रूप में प्रयोग करता हूँ
        var lines = File.ReadAllLines(page);

        // Get the title from the first line
        var title = lines.Length > 0 ? Markdown.ToPlainText(lines[0].Trim()) : string.Empty;
चूंकि शीर्षक "#" के साथ उपसर्ग है, मैं मार्कडाउन विधि का प्रयोग करता हूँ
- श्रेणियों को निकालें प्रत्येक पोस्ट में दो श्रेणियों तक हो सकता है यह विधि इन को निकालती है तो मैं निशान डाउन फ़ाइल से उस टैग को हटाता हूँ
// Concatenate the rest of the lines with newline characters
        var restOfTheLines = string.Join(Environment.NewLine, lines.Skip(1));

        // Extract categories from the text
        var categories = GetCategories(restOfTheLines);

   // Remove category tags from the text
        restOfTheLines = CategoryRegex.Replace(restOfTheLines, "");
GetCategories विधि एक नियमित अभिव्यक्ति का उपयोग करता है कि मार्कडाउन फ़ाइल से श्रेणियों को निकालें
    private static readonly Regex CategoryRegex = new(@"<!--\s*category\s*--\s*([^,]+?)\s*(?:,\s*([^,]+?)\s*)?-->",
        RegexOptions.Compiled | RegexOptions.Singleline);

    private static string[] GetCategories(string markdownText)
    {
        var matches = CategoryRegex.Matches(markdownText);
        var categories = matches
            .SelectMany(match => match.Groups.Cast<Group>()
                .Skip(1) // Skip the entire match group
                .Where(group => group.Success) // Ensure the group matched
                .Select(group => group.Value.Trim()))
            .ToArray();
        return categories;


    }
- प्रकाशित तिथि निकालें तब मैं पोस्ट से तारीख को निकालता हूँ (मैं बनाया गया तारीख का उपयोग कर रहा था लेकिन कैसे मैं इसे एक पूरी डकर छवि के प्रयोग से लागू करता है इसका मतलब यह है कि यह नहीं है यह एक टैग का विश्लेषण करता है जो प्रत्येक .md फ़ाइल में है
     private static readonly Regex DateRegex = new(
        @"<datetime class=""hidden"">(\d{4}-\d{2}-\d{2}T\d{2}:\d{2})</datetime>",
        RegexOptions.Compiled | RegexOptions.IgnoreCase | RegexOptions.NonBacktracking);

           var publishedDate = fileInfo.CreationTime;
        var publishDate = DateRegex.Match(restOfTheLines).Groups[1].Value;
        if (!string.IsNullOrWhiteSpace(publishDate))
            publishedDate = DateTime.ParseExact(publishDate, "yyyy-MM-ddTHH:mm", CultureInfo.InvariantCulture);


        restOfTheLines = DateRegex.Replace(restOfTheLines, "");
- सामग्री निकालें वास्तव में सामग्री प्राप्त करना काफी सरल है यह उपरोक्त छवि टैग प्रतिस्थापन के लिए एक पाइपलाइन का उपयोग करता है।
    pipeline = new MarkdownPipelineBuilder().UseAdvancedExtensions().Use<ImgExtension>().Build();

   var processed =
            html ? Markdown.ToHtml(restOfTheLines, pipeline) : Markdown.ToPlainText(restOfTheLines, pipeline);
प्राप्त करें 'slug यह सिर्फ एक्सटेंशन के बिना फ़ाइलनाम है:
    private string GetSlug(string fileName)
    {
        var slug = System.IO.Path.GetFileNameWithoutExtension(fileName);
        return slug.ToLowerInvariant();
    }
सामग्री वापस करें अब हमारे पास एक पृष्ठ सामग्री है जो हम ब्लॉग के लिए प्रदर्शित कर सकते हैं
The GetPage Method
public (string title, string slug, DateTime publishDate, string processed, string[] categories, string
        restOfTheLines) GetPage(string page, bool html)
    {
        var fileInfo = new FileInfo(page);

        // Ensure the file exists
        if (!fileInfo.Exists) throw new FileNotFoundException("The specified file does not exist.", page);

        // Read all lines from the file
        var lines = File.ReadAllLines(page);

        // Get the title from the first line
        var title = lines.Length > 0 ? Markdown.ToPlainText(lines[0].Trim()) : string.Empty;

        // Concatenate the rest of the lines with newline characters
        var restOfTheLines = string.Join(Environment.NewLine, lines.Skip(1));

        // Extract categories from the text
        var categories = GetCategories(restOfTheLines);

        var publishedDate = fileInfo.CreationTime;
        var publishDate = DateRegex.Match(restOfTheLines).Groups[1].Value;
        if (!string.IsNullOrWhiteSpace(publishDate))
            publishedDate = DateTime.ParseExact(publishDate, "yyyy-MM-ddTHH:mm", CultureInfo.InvariantCulture);

        // Remove category tags from the text
        restOfTheLines = CategoryRegex.Replace(restOfTheLines, "");
        restOfTheLines = DateRegex.Replace(restOfTheLines, "");
        // Process the rest of the lines as either HTML or plain text
        var processed =
            html ? Markdown.ToHtml(restOfTheLines, pipeline) : Markdown.ToPlainText(restOfTheLines, pipeline);

        // Generate the slug from the page filename
        var slug = GetSlug(page);


        // Return the parsed and processed content
        return (title, slug, publishedDate, processed, categories, restOfTheLines);
    }
     public List<PostListModel> GetPosts(string[] pages)
    {
        List<PostListModel> pageModels = new();

        foreach (var page in pages)
        {
            var pageInfo = GetPage(page, false);

            var summary = Markdown.ToPlainText(pageInfo.restOfTheLines).Substring(0, 100) + "...";
            pageModels.Add(new PostListModel
            {
                Categories = pageInfo.categories, Title = pageInfo.title,
                Slug = pageInfo.slug, WordCount = WordCount(pageInfo.restOfTheLines),
                PublishedDate = pageInfo.publishDate, Summary = summary
            });
        }

        pageModels = pageModels.OrderByDescending(x => x.PublishedDate).ToList();
        return pageModels;
    }


    public List<PostListModel> GetPostsForFiles()
    {
        var pages = Directory.GetFiles("Markdown", "*.md");
        return GetPosts(pages);
    }