


تنفيذ سريع لمبادرة " API " ينسخ على وجه السرعة مشروع " API " من برنامج " EasyNMT " (https://github.com/UKPLAB/EasyNMT) وهو مشروع ممتاز ولكنه مهجور للترجمة العصبية - الميكانيكية.
لكنني أضفت الكثير من الميزات اللطيفة لزيادة الموثوقية وجعلها جاهزة للاستخدام في نظام الإنتاج.......................................................................................................................).
منذ بداية هذه المدونة، كان هناك شغف كبير بكتابة مقالات مدونة ذاتية الترجمة.
نعم أنا أعرف أن "جوجل يفعل هذا" في المتصفحات ............................ ....................................................................................................................................................................................................................................................................................................................................................................................mostlylucid-nmtأردت أن أعرف كيف أفعل ذلك!
بالإضافة إلى أنه من الجميل أن نرحب بالناس الذين لا يقرأون الإنجليزية (حتى لو قرأوا الإنجليزية كلغة ثانية، فمن الصعب جداً التعبير عنها).لذلك عملت على كيفية القيام بذلك، وكذلك تقاسم كيفية بناء هذا النوع من النظام.وأعطاني أفكاراً عن كيفية استخدامه في نظام ASP.NET من أجل تحديد موقع النص تلقائياً (بما في ذلك النص الدينامي) باستخدام نظام SignalR ونظام تحديث آني للبقعة.
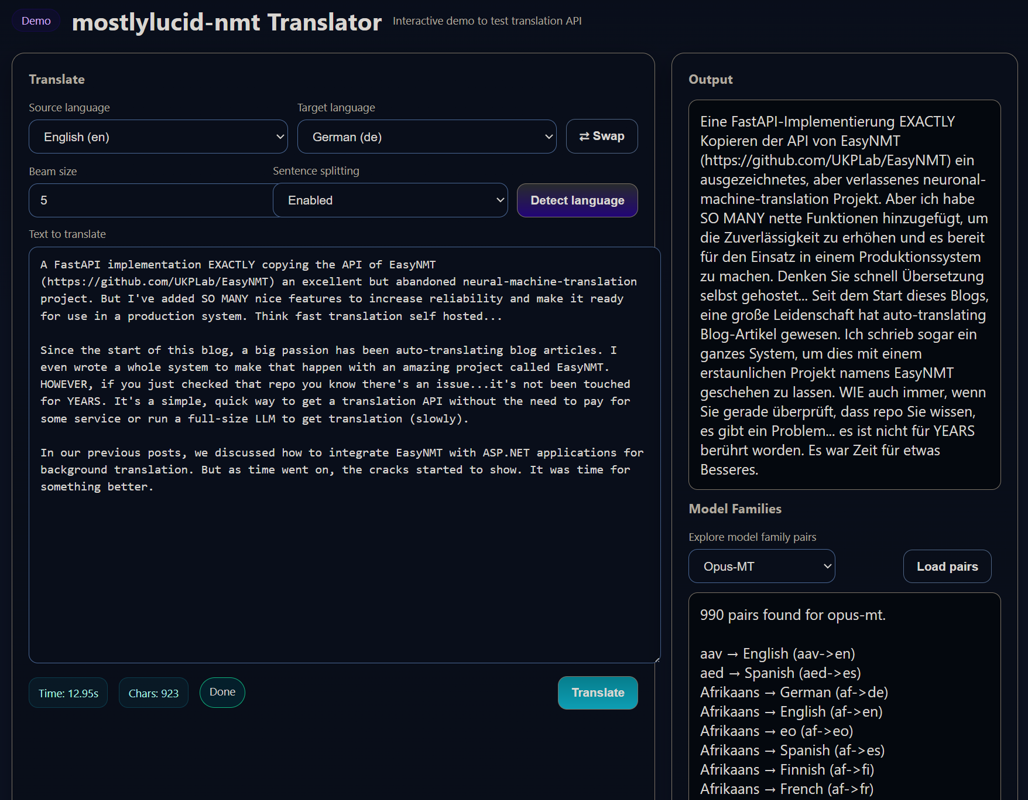
! مُبقاً مُلزماًوقد قدمت عرضاً عملياً هنا؛ https://nmtdemo.mostalylucid.net/demo/ هو يعمل فقط في حاسوب محمول قديم بدون GPUP لكن يعطيك الفكرة (ودعني أختبر اللينجيفايتي).في الاساس ، يكتب البشر نصوصا تافهة تُوجَه الى الآلات لتتعامل معها بكفاءة .
لذا كان الكثير هو معرفة كيفية العمل حول القضايا مع واي نمت (كان في الواقع مشروع بحثي).


(أ)كتب نظاماً كاملاًhttp://<server>:<port>/demoلجعل ذلك يحدث مع مشروع مدهش يسمى "ايزي ناتم"
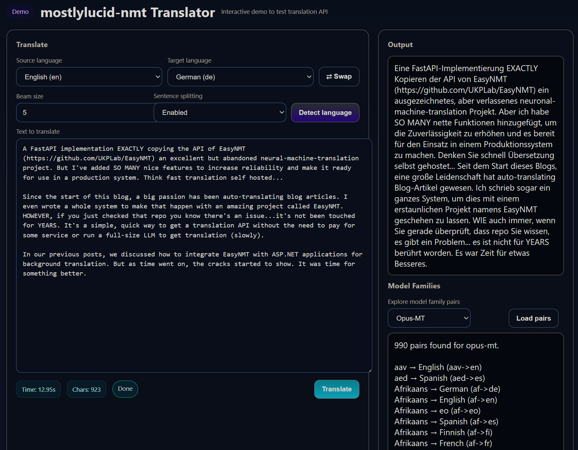
انها طريقة بسيطة وسريعة للحصول على ترجمة API دون الحاجة لدفع ثمن بعض الخدمة أو تشغيل LLM بحجم كامل للحصول على الترجمة (ببطء).
**ولكن مع مرور الوقت، بدأت الشقوق تظهر.**لقد كان الوقت المناسب لشئ أفضل
**كالمعتاد كل شيء على GetTHub وجميع مجانا للاستخدام ...**مُنْفِك
Reusing loaded model for en->de (3/10 models in cache)Need to load model for en->fr (3/10 models in cache)التحديثات الرئيسية (v3-1) - الاستخبارات والرؤيةجديد في v3.1:
====================================================================================================
  🚀 DOWNLOADING MODEL
  Model: facebook/mbart-large-50-many-to-many-mmt
  Family: mbart50
  Direction: en → bn
  Device: GPU (cuda:0)
  Total Size: 2.46 GB
  Files: 6 main files
====================================================================================================
[Progress bars for each file...]
====================================================================================================
  ✅ MODEL READY
  Model: facebook/mbart-large-50-many-to-many-mmt
  Translation: en → bn is now available
====================================================================================================
**: افتراضي حجم المخبأ مُصَدَف إلى 10 نماذج (من 6)**تاريخ بدء تشغيل الجهاز
[Pivot] Languages reachable from en: 85 languages
[Pivot] Languages that can reach bn: 42 languages
[Pivot] Found 38 possible pivot languages
[Pivot] Selected pivot: en → hi → bn (both legs verified)
يُظهِر جهاز الهدف (GPU/CU) في الواجهة& & & & & & & & & &
Request: en→bn with opus-mt
Trying families: ['opus-mt', 'mbart50', 'm2m100']  ✓ All three!
opus-mt: Failed (model doesn't exist)
mbart50: Success! (auto-fallback worked)
مُنتم مُنت حفظ- لا مزيد من محاولات العمى:
Loading mbart50 model on GPU (cuda:0)Model loaded on device: cuda:0Successfully loaded... on GPU (cuda:0)لن يجرّب ذلك إذا لم تكن الـ esobbn غير موجودةحدث لـ
en->hi, hi->bn[Pivot] Both legs loaded and cached. Ready to translate.: انظر بالضبط لماذا كل محور تم اختياره أو تركهأولاً -
model_familyدائماً يُلا مزيد من إعادة صياغة نفس النموذج مرتين(الإنجاز
**تشتمل الرسالة على ما يلي:**٦ -
**-يعمل مسبقاً في مجال العرض:**DEmo إسقاط نزولي يسمح باختيار أوفوس-mt، أو mbart50، أو m2m100
requirements-prod.txt(بآلاف دولارات الولايات المتحدة)**- حلقة الوصلة البينية التفاعلية المنتجة والواثقة من الإنتاج:**تصميم موقع العرض الكامل (100vw/100vh) للخبرة في مجال الترجمة التحريرية المحفوظة
**: FP16 ممكن ، BATch_Sizee= 64 ، MAX_ INFLLight= 1 (الأفضل لـ واحد GPU)**وحدة وحدة
**- صور أصغر وأسرع:**نقاط اعتماد الاختبار المزالة (Bybet, Pyyytest- cov) من بناء الإنتاج
اختبار و اختبار التحميل- صحة كل شيء:
مع وجود أنماط حركةنصات مصادق مصادقات
/discover/opus-mt(الدولة الصهـر + باش)/discover/mbart50إختبارات تنزيلات نموذج و ترجمة محوريّة إلى الخلف/discover/m2m100اختبارات التدخين الآلية للمصادقة السريعة5 - مكتب الأمم المتحدة في نيويورك
بيانات كوبرنيت مع كلوريد البوليفينيل، حدود الموارد، الفحوص الصحيةأمثلة على ذلك
scottgal/mostlylucid-nmt:cpuتوجيهات الاختبار وتوصيات الرصد:latestمعاملات مقايضة مقايضةscottgal/mostlylucid-nmt:cpu-min٦ -scottgal/mostlylucid-nmt:gpuجيم - الأسر النموذجية الثلاثscottgal/mostlylucid-nmt:gpu-min- اختيار الأفضل لاحتياجاتك:الإسناد - الأمتام> 1200+ أزواج، أفضل جودة (نماذج منفصلة)
latest, min, gpu, gpu-min:50 لغة، نموذج واحد 2.4 ميغاواط، 450 2 زوجاً20250108.143022: 100 لغة، نموذج واحد 2.2GB، 9 900 زوجأنت هذا هذا- أفضل نموذج متاح للاختيارات الذكية:
- جميع أزواج MBARTART50- جميع ازواج M2MM100
لا توجد نماذج سبق تحميلها (الخفض عند الطلب)
الأسر النموذجية بدون إعادة بناء10 - لا شيءمُنتزِل المُرَفْفِز
cpu(فيlatest) | scottgal/mostlylucid-nmt:cpu- مُسْلَك
| cpu-min | scottgal/mostlylucid-nmt:cpu-min- مُقْصَل الحد الأدنى
| gpu | scottgal/mostlylucid-nmt:gpu- المعالج مع الكودا 12.6 12
| gpu-min | scottgal/mostlylucid-nmt:gpu-min- الحد الأدنى١١ -التصيـل
كامل OCI لـ متابعة إصدارات و بناء التواريخ و get
docker run -d \
  --name mostlylucid-nmt \
  -p 8000:8000 \
  scottgal/mostlylucid-nmt
الـمــن الــعــن الــ
curl -X POST "http://localhost:8000/translate" \
  -H "Content-Type: application/json" \
  -d '{
    "text": ["Hello, how are you?"],
    "target_lang": "de"
  }'
لا دعم
{
  "translated": ["Hallo, wie geht es Ihnen?"],
  "target_lang": "de",
  "source_lang": "en",
  "translation_time": 0.34
}
بايثون 3-12-سليم
docker run -d \
  --name mostlylucid-nmt \
  --gpus all \
  -p 8000:8000 \
  -e EASYNMT_MODEL_ARGS='{"torch_dtype":"fp16"}' \
  scottgal/mostlylucid-nmt:gpu
الطفل ٢١٦
مع أوبونتو 24.04 لصور GPU (Lates NVIDIA كومة)
docker run -d \
  --name mostlylucid-nmt \
  -p 8000:8000 \
  -v $HOME/model-cache:/models \
  -e MODEL_CACHE_DIR=/models \
  scottgal/mostlylucid-nmt:cpu-min
PyTorch مع CUDA 12.4
docker run -d `
  --name mostlylucid-nmt `
  -p 8000:8000 `
  -v ${HOME}/model-cache:/models `
  -e MODEL_CACHE_DIR=/models `
  scottgal/mostlylucid-nmt:cpu-min
(متوافق مع CUDA 12.6 وقت تشغيل)
docker run -d ^
  --name mostlylucid-nmt ^
  -p 8000:8000 ^
  -v %USERPROFILE%/model-cache:/models ^
  -e MODEL_CACHE_DIR=/models ^
  scottgal/mostlylucid-nmt:cpu-min
تُحدِّث جميع
13 -
curl http://localhost:8000/healthz
تحذيرات الاستهلاك الثابت
(يستخدم حالياً HF_ HOME)متوافق مع المطورات v 5البداية السريعة (5 دقائق)
http://localhost:8000/demo/
هذه هي الطريقة المبسطة المطلقة لتشغيل moslucid-nmt:
مور منفذ
الاسم الكامل للصورة: الحجم / الوصف / حالة استخدام الحالة /
الصور
ابقاء الحاويات صغيرة الحجم
يتطلّب NVIDIA DOkkr وقت التشغيل:
الفحص الصحي:
١ -
// Example: Translating a 5000-word article
Input: Long article with multiple paragraphs

Step 1: Split by paragraphs (preserves structure)
  → Paragraph 1 (800 chars)
  → Paragraph 2 (1200 chars)
  → Paragraph 3 (600 chars)
  ...

Step 2: Group into ~1000 character chunks
  → Chunk 1: Paragraphs 1-2
  → Chunk 2: Paragraph 3-4
  → Chunk 3: Paragraphs 5-6

Step 3: Translate each chunk sequentially
  → Shows progress: "Translating chunk 1/3..."
  → Shows progress: "Translating chunk 2/3..."
  → Shows progress: "Translating chunk 3/3..."

Step 4: Reassemble with paragraph breaks
  → Final output: Complete translated article with preserved formatting
إسقاطات اللغة المكتوبة ذاتياً من الخدمة الحية
مناولة تلقائيًا مدخلات نص كبيرة من أي حجم
أولاً -
متقدم:
****:
إحصاءات الوقت الحقيقي:
ترجمة ترجمة تحرير/فعل/أجور
: ١٠٠ لغــة، ٩ ٩٠٠ زوج/demo/انظر بدقة ما هي اللغات التي توجد فيها أزواج متاحة قبل الترجمة
الـ عرض تنفيذيّات s نص ذكيّ نص يعمل عميل جانب:لماذا تستخدم الديمو؟الاختبار السريعالترجماتمدى التوافر
مقارنة جودة الترجمة مع مختلف أحجام العرض
مُدَوَّلَةً كاملةً مُدَرَّجَةً (5000 + 5)DEmo آلياً يقسمها إلى قطع قابلة للتصريفإظهار التقدم ك كلفك
اللغةنص اللصق بلغة مجهولةانقر "انقر"
لا ضغـط في الظهـر الرجعـي أو فـي الطـاولاتإرسال الكثير من الطلبات و هو فقط يَكْليلُ أكثر من اللازمُ.MODEL_FAMILYلا وجود لملاحظات.
# Opus-MT (default, best quality)
MODEL_FAMILY=opus-mt

# mBART50 (50 languages, single model)
MODEL_FAMILY=mbart50

# M2M100 (100 languages, broadest coverage)
MODEL_FAMILY=m2m100
الحل: في الغالب لوسد- ن ملذا قررت أن أبني طريقة جديدة ومحسنةCFsCed- nmt
MODEL_FAMILYوهنا ما يجعلها أفضل:opus-mtدعم الأسرة المتعددةأوفus-MT (Helsinki- NLLLLL) - افتراض
# Set primary to Opus-MT (best quality)
MODEL_FAMILY=opus-mt
AUTO_MODEL_FALLBACK=1
MODEL_FALLBACK_ORDER=opus-mt,mbart50,m2m100

# Request Ukrainian → French
# 1. Try Opus-MT first (not available)
# 2. Automatically fall back to mBART50 (available!)
# 3. Translation succeeds with mBART50
التغطية:
٣٠٠-٥٠٠ ميغا ف/
# Enable auto-fallback (default: enabled)
AUTO_MODEL_FALLBACK=1

# Set fallback priority (default: opus-mt → mbart50 → m2m100)
MODEL_FALLBACK_ORDER="opus-mt,mbart50,m2m100"

# Disable for strict single-family mode
AUTO_MODEL_FALLBACK=0
مثال:
-min& هذا العرض:الميزة:
المُحْدِث سهل
واحدة من أقوى الميزات الجديدة
**كيف يعمل:**أنت تعيين a
الاستحقاقات:
دعم 100 + 100 لغة بدون إدارة عمليات نشر متعددة
(أ) قطع الأشجار بصورة شفافة:
دعم الأسرة المتعددة النماذج
# NMT: Fits on a USB stick
du -sh model-cache/
2.5G    model-cache/

# LLM: Needs serious storage
du -sh llama-models/
140G    llama-models/
نقاط النهاية النموذجية للاكتشاف
ماذا؟
LRRL نموذج كَسِج
مؤشر أسعار الصرف المتوافق مع السهل والمتوافق مع الميـز
(ب) بدائل مع مخابئ الحجم المكشوف لعمليات النشر الأصغر حجماً.
لِمَ يُمْكِنُ أَنْ تُشَجِّعَ ٱلْمَلَكَاتِ عَلَى ٱلْمَلَكَاتِ لِلْتِجَارَةِ ؟
Input: "The API returns a 429 status code when rate limited."

NMT (Opus-MT): "Die API gibt einen 429-Statuscode zurück, wenn sie ratenbegrenzt ist."
(Accurate, preserves technical terms)

LLM (might do): "Die API sendet den Fehlercode 429, wenn zu viele Anfragen gestellt werden."
(Interprets rather than translates, adds context not in original)
هذا هو التحقق الواقعي بناء على استخدام الإنتاج:
GPT-4: 3-10 ثوان لكل طلب (التوليد)
النسبة المئوية**:: 30 - 60 ثانية**
Opus-MT (للاتجاه): 300-500 ميغ ميغ ميغابايت
MBART50 (اللغات الـ 50): 2.4GBM2M100 (باللغات المائة): 2.2GB
flowchart LR
    A[HTTP Client] --> B[API Gateway]
    B --> C[Translation Endpoint]
    C --> D{Has Capacity?}
    D -->|Yes| E[Translation Service]
    D -->|No| F[Queue with 429]
    F --> E
    E --> G[Process Pipeline]
    G --> H[Get Model from Cache]
    H --> I[Translate]
    I --> J[Return Response]
    J --> A
LLLLs:
Retry-Afterالتكلفة: ١٠-٢٠ في الشهر**مواطن القوة:**مُدربة خصيصا للترجمةRetry-Afterثبات الجودة (مضضضض جودة)
لا حاجة إلى تكاليف هندسية
sequenceDiagram
    participant Client
    participant API
    participant Queue
    participant Translator
    participant Cache
    participant Model

    Client->>API: POST /translate
    API->>Queue: Acquire slot

    alt Queue has space
        Queue-->>API: Slot acquired
        API->>Translator: Process translation
        Translator->>Translator: Sanitize input
        Translator->>Translator: Split sentences
        Translator->>Translator: Chunk text
        Translator->>Translator: Mask symbols
        Translator->>Cache: Get model (en→de)

        alt Cache hit
            Cache-->>Translator: Return cached model
        else Cache miss
            Cache->>Model: Load from Hugging Face
            Model-->>Cache: Pipeline loaded
            Cache->>Cache: Evict old if at capacity
            Cache-->>Translator: Return model
        end

        Translator->>Model: Translate batches
        Model-->>Translator: Translations
        Translator->>Translator: Unmask symbols
        Translator->>Translator: Post-process
        Translator-->>API: Translations
        API->>Queue: Release slot
        API-->>Client: 200 OK + translations
    else Queue full
        Queue-->>API: Overflow error
        API-->>Client: 429 Too Many Requests\nRetry-After: X seconds
    end
السيناريو:
graph LR
    A[Raw Input] --> B{Sanitize?}
    B -->|Yes| C[Check Noise]
    B -->|No| D[Split Sentences]
    C -->|Is Noise| Z[Return Placeholder]
    C -->|Valid| D

    D --> E[Enforce Max Length]
    E --> F[Chunk for Batching]
    F --> G{Symbol Masking?}

    G -->|Yes| H[Mask Digits/Punct/Emoji]
    G -->|No| I[Translate]
    H --> I

    I --> J{Direct Model?}
    J -->|Available| K[Direct Translation]
    J -->|Not Available| L{Pivot Fallback?}

    L -->|Yes| M[src→en→tgt]
    L -->|No| Z
    K --> N[Unmask Syis robust input handling. Here's what happens:

**Noise Detection:**
- Strips control characters (except \t, \n, \r)
- Checks minimum character count (default: 1)
- Calculates alphanumeric ratio (default: must be ≥20%)
- Rejects pure emoji, pure punctuation, or pure whitespace

**Symbol Masking:**
Why mask symbols? Translation models are trained on text, not emoji or special symbols. These can confuse them or get mangled. So we:

1. Extract all digits, punctuation, and emoji as contiguous runs
2. Replace them with sentinel tokens: `⟪MSK0⟫`, `⟪MSK1⟫`, etc.
3. Translate the masked text
4. Restore the original symbols in their positions

Example:
Input: "Hello 👋 world! Price: $99.99" متى إلى استخدام (👋) (!) (:) ($99.99)
**Post-Processing:**
After translation, we remove "symbol loops" - repeated symbols that weren't in the source:
استخدام نف إمت (معظماً لوثود- نتمت) عندما: تحتاج إلى مُتّسق، مُترجم سريع في الحجم المسائل (الميزانية المستضيفة ذاتياً أو كبيرة الحجم)
### Sentence Splitting & Chunking

Long texts get split intelligently:

```mermaid
graph TD
    A[Long Text] --> B[Split on . ! ? …]
    B --> C{Sentence > 500 chars?}
    C -->|Yes| D[Split on word boundaries]
    C -->|No| E[Keep sentence]
    D --> E

    E --> F[Group into chunks ≤900 chars]
    F --> G[Translate each chunk]
    G --> H[Join with space]
أنت تُترجم المحتوى التقني، الرمز، البيانات المُنَظَّمة
تحتاج إلى تكييف إبداعي، لا ترجمة حرفية
stateDiagram-v2
    [*] --> CheckCache
    CheckCache --> CacheHit: Model exists
    CheckCache --> CacheMiss: Model not loaded

    CacheHit --> MoveToEnd: Update LRU order
    MoveToEnd --> ReturnModel

    CacheMiss --> CheckCapacity
    CheckCapacity --> LoadModel: Space available
    CheckCapacity --> EvictOldest: Cache full

    EvictOldest --> MoveToCPU: Free VRAM
    MoveToCPU --> ClearCUDA: torch.cuda.empty_cache()
    ClearCUDA --> LoadModel

    LoadModel --> AddToCache
    AddToCache --> ReturnModel
    ReturnModel --> [*]
أكثر من السرعة
(حالة استخدامي)، NMT هو الفائز الواضح:
# Semaphore limits concurrent translations
MAX_INFLIGHT = 1  # On GPU, 1 at a time for efficiency
MAX_QUEUE_SIZE = 1000  # Up to 1000 waiting

# When full:
# - Returns 429 Too Many Requests
# - Includes Retry-After header
# - Estimates wait time based on average duration
ترجمة 100 أكثر من 100 تدوينة إلى 12 لغة في حوالي 30 دقيقة (GPU)
avg_duration = 2.5 seconds (tracked with EMA)
waiters = 100
slots = 1
estimated_wait = (100 / 1) * 2.5 = 250 seconds
clamped = min(250, 120) = 120 seconds
Retry-After: 120
وجودة متسقة بين جميع الوظائف
graph LR
    A[Ukrainian Text] --> B{Direct uk→fr?}
    B -->|Exists| C[Translate Directly]
    B -->|Missing| D[Pivot via English]

    D --> E[uk→en]
    E --> F[en→fr]
    F --> G[French Result]
    C --> G
مجموع المبلغ الإجمالي: حاوية واحدة من طراز DOcker
والفرق في السرعة وحده يجعل من النقل غير المشروع هو الخيار العملي الوحيد لخطوط أنابيب ترجمة الإنتاج.
NMT مصمّم للترجمة، يعمل على أجهزة متواضعة، وهو أسرع من LLMs بمقدار 10. إذا كنت بحاجة إلى ترجمة سريعة ومتسقة وفعالة من حيث التكلفة على النطاق، فإن NMT ينتصر.
# src/core/cache.py
from collections import OrderedDict
import torch

class LRUPipelineCache:
    """LRU cache that automatically cleans up GPU memory when evicting models."""

    def __init__(self, capacity: int):
        self.cache = OrderedDict()  # Maintains insertion order
        self.capacity = capacity

    def get(self, key: str):
        """Get model from cache, moves it to end (most recently used)."""
        if key not in self.cache:
            return None
        self.cache.move_to_end(key)  # Mark as recently used
        return self.cache[key]

    def put(self, key: str, value):
        """Add model to cache, evicting oldest if at capacity."""
        if key in self.cache:
            self.cache.move_to_end(key)
        else:
            self.cache[key] = value

        # If cache is full, evict the oldest model
        if len(self.cache) > self.capacity:
            oldest_key, oldest_pipeline = self.cache.popitem(last=False)

            # MAGIC: Move evicted model to CPU to free GPU memory
            try:
                oldest_pipeline.model.to("cpu")
                if torch.cuda.is_available():
                    torch.cuda.empty_cache()  # Tell GPU to release memory
                logger.info(f"Evicted {oldest_key}, freed GPU memory")
            except Exception as e:
                logger.warning(f"Failed to clean GPU memory: {e}")
أولاً - لمحة عامة
OrderedDictوتدفق الطلب واضح:الطلب موجه إلى دائرة الترجمة الفورية
# src/services/model_manager.py
def get_pipeline(self, src: str, tgt: str):
    """Try to get translation model, with automatic fallback to other providers."""

    # Determine which model families support this language pair
    families_to_try = []

    if config.AUTO_MODEL_FALLBACK:
        # Try families in priority order: opus-mt → mbart50 → m2m100
        for family in config.MODEL_FALLBACK_ORDER.split(","):
            if self._is_pair_supported(src, tgt, family.strip()):
                families_to_try.append(family.strip())

    # Try each family until one succeeds
    last_error = None
    for family in families_to_try:
        try:
            model_name, src_lang, tgt_lang, _ = self._get_model_name_and_langs(src, tgt, family)

            if family != config.MODEL_FAMILY:
                logger.info(f"Using fallback '{family}' for {src}->{tgt}")

            # Load the model from HuggingFace
            pipeline = transformers.pipeline(
                "translation",
                model=model_name,
                device=device_manager.device_index,
                src_lang=src_lang,
                tgt_lang=tgt_lang
            )

            self.cache.put(f"{src}->{tgt}", pipeline)
            return pipeline

        except Exception as e:
            last_error = e
            logger.warning(f"Family '{family}' failed for {src}->{tgt}: {e}")
            continue  # Try next family

    # All families failed
    raise ModelLoadError(f"{src}->{tgt}", last_error)
رقم رقم:
(LRU) توفر نماذج للترجمة:
# src/services/queue_manager.py
import asyncio
from contextlib import asynccontextmanager

class QueueManager:
    """Manages request queuing and backpressure."""

    def __init__(self, max_inflight: int, max_queue: int):
        self.semaphore = asyncio.Semaphore(max_inflight)  # Limit concurrent translations
        self.max_queue_size = max_queue
        self.waiting_count = 0
        self.inflight_count = 0
        self.avg_duration_sec = 5.0  # Exponential moving average

    @asynccontextmanager
    async def acquire_slot(self):
        """Try to get a translation slot, track metrics, handle queueing."""

        # Check if queue is too full
        if self.waiting_count >= self.max_queue_size:
            # Calculate how long client should wait before retrying
            retry_after = self._estimate_retry_after()
            raise QueueOverflowError(self.waiting_count, retry_after)

        self.waiting_count += 1
        try:
            # Wait for available slot (this is the queue!)
            await self.semaphore.acquire()
            self.waiting_count -= 1
            self.inflight_count += 1

            start_time = time.time()
            yield  # Let the translation happen

            # Update average duration for retry-after estimates
            duration = time.time() - start_time
            alpha = config.RETRY_AFTER_ALPHA  # Smoothing factor (0.2)
            self.avg_duration_sec = alpha * duration + (1 - alpha) * self.avg_duration_sec

        finally:
            self.inflight_count -= 1
            self.semaphore.release()

    def _estimate_retry_after(self) -> int:
        """Smart calculation: how many waiting / how many slots * avg time per request."""
        if self.inflight_count == 0:
            return config.RETRY_AFTER_MIN_SEC

        # If 10 people waiting and 2 slots available, and each takes 5 seconds:
        # retry_after = (10 / 2) * 5 = 25 seconds
        retry_sec = (self.waiting_count / self.semaphore._value) * self.avg_duration_sec

        # Clamp between min and max
        return max(
            config.RETRY_AFTER_MIN_SEC,
            min(int(retry_sec), config.RETRY_AFTER_MAX_SEC)
        )
الملصقات التي تم ضربها(أ) الاستجابة السريعة
max_inflight)@asynccontextmanagerترجع إلى العميلتمّ تنفيذ
# src/utils/symbol_masking.py
import re

def mask_symbols(text: str) -> tuple[str, dict[str, str]]:
    """Replace special symbols with placeholders before translation."""

    originals = {}
    masked_text = text
    placeholder_counter = 0

    # Pattern: Match emojis, symbols, special punctuation
    # \U0001F300-\U0001F9FF = emoji range
    # [\u2600-\u26FF\u2700-\u27BF] = misc symbols
    symbol_pattern = re.compile(
        r'[\U0001F300-\U0001F9FF\u2600-\u26FF\u2700-\u27BF'
        r'\u00A9\u00AE\u2122\u2139\u3030\u303D\u3297\u3299]+'
    )

    for match in symbol_pattern.finditer(text):
        symbol = match.group()
        placeholder = f"__SYMBOL_{placeholder_counter}__"
        originals[placeholder] = symbol
        masked_text = masked_text.replace(symbol, placeholder, 1)
        placeholder_counter += 1

    return masked_text, originals

def unmask_symbols(text: str, originals: dict[str, str]) -> str:
    """Restore original symbols after translation."""
    for placeholder, original in originals.items():
        text = text.replace(placeholder, original)
    return text
تستخدم هذه الخدمة خط أنابيب متطور متعدد المراحل للتعامل مع النص الواقعي الفوضوي:
# Before translation:
text = "Hello! 👋 Check out this cool feature 🚀"

# Mask symbols:
masked, originals = mask_symbols(text)
# masked = "Hello! __SYMBOL_0__ Check out this cool feature __SYMBOL_1__"
# originals = {"__SYMBOL_0__": "👋", "__SYMBOL_1__": "🚀"}

# Translate the masked text:
translated = translate(masked, "de")  # → "Hallo! __SYMBOL_0__ Schau dir diese coole Funktion an __SYMBOL_1__"

# Unmask symbols:
final = unmask_symbols(translated, originals)
# final = "Hallo! 👋 Schau dir diese coole Funktion an 🚀"
مُسَسَّق: "مرحباً، EMSK01، العالم ISMSK1، السعر EMSMSK2 o EMSK3"
👋النماذج لا تخنق المدخلات الضخمة__SYMBOL_0__يمكننا أن ندفع بكفاءةولهذا السبب فإن هذا يهم:
# src/utils/text_processing.py
def chunk_sentences(sentences: list[str], max_chars: int = 900) -> list[list[str]]:
    """Group sentences into chunks that fit within model's max input length."""

    chunks = []
    current_chunk = []
    current_length = 0

    for sentence in sentences:
        sentence_len = len(sentence)

        # If this sentence alone is too long, it goes in its own chunk
        if sentence_len > max_chars:
            if current_chunk:
                chunks.append(current_chunk)
                current_chunk = []
                current_length = 0
            chunks.append([sentence])
            continue

        # If adding this sentence exceeds limit, start new chunk
        if current_length + sentence_len + 1 > max_chars:
            chunks.append(current_chunk)
            current_chunk = [sentence]
            current_length = sentence_len
        else:
            current_chunk.append(sentence)
            current_length += sentence_len + 1  # +1 for space

    # Don't forget the last chunk!
    if current_chunk:
        chunks.append(current_chunk)

    return chunks

def split_sentences(text: str, max_sentence_chars: int = 500) -> list[str]:
    """Split text into sentences, enforcing max length."""

    # Split on common sentence terminators
    sentences = re.split(r'([.!?…]+\s+)', text)

    result = []
    for sentence in sentences:
        if not sentence or sentence.isspace():
            continue

        # If sentence is too long, split on word boundaries
        if len(sentence) > max_sentence_chars:
            words = sentence.split()
            current = []
            current_len = 0

            for word in words:
                if current_len + len(word) + 1 > max_sentence_chars:
                    result.append(' '.join(current))
                    current = [word]
                    current_len = len(word)
                else:
                    current.append(word)
                    current_len += len(word) + 1

            if current:
                result.append(' '.join(current))
        else:
            result.append(sentence.strip())

    return result
ذاكرة GPU هي قيمة
.!?…نُبقي الـ 6 نماذج الأخيرة مُثيرةمحوري من خلال الإنكليزية:
# src/services/model_discovery.py
import httpx
from datetime import datetime, timedelta

class ModelDiscoveryService:
    """Discovers available translation models with 1-hour cache."""

    def __init__(self):
        self._cache = {}  # Cache results to avoid hammering HuggingFace API
        self._cache_ttl = timedelta(hours=1)
        self._hf_api_base = "https://huggingface.co/api/models"

    async def discover_opus_mt_pairs(self, force_refresh: bool = False):
        """Query HuggingFace for all Helsinki-NLP Opus-MT models."""

        cache_key = "opus-mt"

        # Check cache first
        if not force_refresh and cache_key in self._cache:
            cached_data, cached_time = self._cache[cache_key]
            if datetime.now() - cached_time < self._cache_ttl:
                return cached_data  # Cache hit!

        # Cache miss - query HuggingFace API
        async with httpx.AsyncClient() as client:
            response = await client.get(
                self._hf_api_base,
                params={
                    "author": "Helsinki-NLP",
                    "search": "opus-mt",
                    "limit": 1000
                },
                timeout=30.0
            )
            models = response.json()

        # Extract language pairs from model names
        # Example: "Helsinki-NLP/opus-mt-en-de" → ("en", "de")
        pairs = []
        for model in models:
            model_id = model.get("modelId", "")
            if model_id.startswith("Helsinki-NLP/opus-mt-"):
                # Extract the language codes after "opus-mt-"
                lang_part = model_id.replace("Helsinki-NLP/opus-mt-", "")
                if "-" in lang_part:
                    src, tgt = lang_part.split("-", 1)
                    pairs.append({"source": src, "target": tgt})

        # Cache the results
        self._cache[cache_key] = (pairs, datetime.now())

        return pairs
وهذا التأخير المزدوج يكفل تغطية جميع أزواج اللغات المدعومة.
httpxدعونا نستكشف بعض من أكثر الأجزاء إثارة للاهتمام من قاعدة الشفرات!enواحدة من أروع الميزات هي نموذج المخبأ الذكي الذي يعرف كيفية التعامل مع ذاكرة GPU:deما الذي يحدث هنا؟Helsinki-NLP/opus-mt-en-deتنظيف GPU
# src/core/device.py
import torch

class DeviceManager:
    """Smart device selection with GPU auto-detection."""

    def __init__(self):
        self.use_gpu = self._should_use_gpu()
        self.device_index = self._resolve_device()
        self.device_str = "cpu" if self.device_index < 0 else f"cuda:{self.device_index}"

        # Auto-configure parallel translation slots based on device
        if self.device_index >= 0:
            # GPU: Run translations serially to avoid VRAM fragmentation
            self.max_inflight = 1
        else:
            # CPU: Can handle multiple translations in parallel
            self.max_inflight = config.MAX_WORKERS_BACKEND

        self._log_device_info()

    def _should_use_gpu(self) -> bool:
        """Check if GPU should be used."""
        if config.USE_GPU.lower() == "false":
            return False
        if config.USE_GPU.lower() == "true":
            return torch.cuda.is_available()
        # "auto" mode: use GPU if available
        return torch.cuda.is_available()

    def _resolve_device(self) -> int:
        """Returns device index: -1 for CPU, 0+ for CUDA."""
        if not self.use_gpu:
            return -1

        # Check if specific CUDA device requested
        if config.DEVICE and config.DEVICE.startswith("cuda:"):
            device_num = int(config.DEVICE.split(":")[1])
            return device_num

        return 0  # Use first GPU

    def _log_device_info(self):
        """Log device information at startup."""
        if self.device_index >= 0:
            gpu_name = torch.cuda.get_device_name(self.device_index)
            vram_gb = torch.cuda.get_device_properties(self.device_index).total_memory / 1e9
            logger.info(f"Using GPU: {gpu_name} ({vram_gb:.1f}GB VRAM)")
            logger.info(f"Max inflight translations: {self.max_inflight} (GPU mode)")
        else:
            cpu_count = os.cpu_count()
            logger.info(f"Using CPU ({cpu_count} cores)")
            logger.info(f"Max inflight translations: {self.max_inflight} (CPU mode)")

# Global singleton instance
device_manager = DeviceManager()
عندما نطرد نموذج ما، ننقله صراحة إلى ذاكرة المعالج ونخبر المعالج أن يحرر موارده
max_inflight=1هذه الميزة الذكية تختبر العديد من مقدمي نماذج AI تلقائياً إذا لم يكن الأول لديه زوج اللغة الذي تحتاجه:max_inflight=4ما الذي يحدث هنا؟DEVICE=cuda:1: نماذج ناجحة مخبئة مع مفتاح زوج اللغة
# Snippet from QueueManager showing EMA calculation
def update_avg_duration(self, new_duration: float):
    """Update average duration using exponential moving average."""

    # EMA formula: new_avg = α × new_value + (1 - α) × old_avg
    # α = smoothing factor (0.0 to 1.0)
    #   - Higher α = more weight to recent values (faster adaptation)
    #   - Lower α = more weight to historical values (more stable)

    alpha = 0.2  # 20% weight to new value, 80% to historical

    self.avg_duration_sec = (
        alpha * new_duration +
        (1 - alpha) * self.avg_duration_sec
    )
أولاً -
# Initial average: 5.0 seconds
# New request takes: 10.0 seconds

# EMA calculation:
new_avg = 0.2 * 10.0 + 0.8 * 5.0
        = 2.0 + 4.0
        = 6.0 seconds

# Next request takes: 3.0 seconds
new_avg = 0.2 * 3.0 + 0.8 * 6.0
        = 0.6 + 4.8
        = 5.4 seconds
طلب تقديم طلب تقديم الطلب مع ضغط ضغط الظهر (HTTTP 429)
Retry-Afterمتوسط تحرّك: مُسَطَبِطَةً مُسْكِبَةً في مدة الطلب
الاحتياجات المؤقتة المؤقتة المؤقتة
: نماذج الترجمة في بعض الأحيان فاسدة أو إزالة الميجوجات - هذا يحافظ عليها بشكل مثالي!
# Prefer GPU if available (default)
USE_GPU=auto

# Force GPU
USE_GPU=true

# Force CPU
USE_GPU=false

# Explicit device override
DEVICE=cuda:0
DEVICE=cpu
# Model family selection (NEW in v2.0!)
MODEL_FAMILY=opus-mt   # Best quality (default)
MODEL_FAMILY=mbart50   # 50 languages, single model
MODEL_FAMILY=m2m100    # 100 languages, maximum coverage

# Auto-fallback between model families (NEW in v2.0!)
AUTO_MODEL_FALLBACK=1  # Enabled by default
MODEL_FALLBACK_ORDER="opus-mt,mbart50,m2m100"  # Priority order

# Volume-mapped model cache (NEW in v2.0!)
MODEL_CACHE_DIR=/models  # Persistent cache directory

# Model arguments passed to transformers.pipeline
EASYNMT_MODEL_ARGS='{"torch_dtype":"fp16"}'
EASYNMT_MODEL_ARGS='{"torch_dtype":"bf16","cache_dir":"/models"}'

# Preload models at startup (reduces first-request latency)
PRELOAD_MODELS="en->de,de->en,fr->en"

# LRU cache capacity
MAX_CACHED_MODELS=6
يقسم نصوص طويلة إلى قطع تناسب حدود النموذج مع حفظ حدود الجملة:
**ما الذي يحدث هنا؟**الدالة الدالة D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D D
opus-mtاستخدامات regex لتقسيمها علىmbart50« مع حفظها » حفظها « وحفاها » حفظا « وحافظاها » تسبيها « وزهاهاها وهاهاهاهاهاها في حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها « و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها و حفظها ، و حفظها و حفظها ، و : في حفظها و حفظها و حفظها و حفظها و حفظها : : : : : : : : : في حفظها و حفظ و : : : : : : في حفظ و : : : : : : و : : : : : : : : : : : حفظ و : : : : : : حفظ و : : : : : : : : : : : : : : : : : و : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : : :m2m100مُجَدَّد مُنْقِق: العبوات بأكبر عدد ممكن من الجمل في كل قطعة دون تجاوز الحدتَمْر و و و و و و و و و
1:إذا كانت الجملة الواحدة طويلة جداً، انقسامات على المساحات بدلاً من قطع كلمة الوسط0السبب في أن الأمر يهم**: نماذج الترجمة لها حدود للمدخلات (عادة 512-1024 رمزا رمزيا).**وهذا يضمن ألا نتجاوزها أبداً بينما نبقي السياق سليماً.
"opus-mt,mbart50,m2m100"مُسند مع كش"m2m100,mbart50,opus-mt"ما الذي يحدث هنا؟****HTTP إلى HugingFace
/modelsيخزن النتائج لساعة واحدة لتجنب الحد من المعدل-v ./model-cache:/modelsوقد عقد مؤتمراً بشأن
fp16سادساbf16السبب في أن الأمر يهمfp32: HitgingFais لديها 1200+ نماذج Opus-MT.# Batch size for translation (higher = faster but more VRAM)
EASYNMT_BATCH_SIZE=16 # CPU: 8-16, GPU: 32-64
# Maximum text length per item
EASYNMT_MAX_TEXT_LEN=1000
# Maximum beam size (higher = better quality but slower)
EASYNMT_MAX_BEAM_SIZE=5
# Worker thread pools
MAX_WORKERS_BACKEND=1 # Translation workers
MAX_WORKERS_FRONTEND=2 # Language detection workers
# Enable request queueing (highly recommended)
ENABLE_QUEUE=1

# Max concurrent translations
# Auto: 1 on GPU, MAX_WORKERS_BACKEND on CPU
MAX_INFLIGHT_TRANSLATIONS=1

# Max queued requests before 429
MAX_QUEUE_SIZE=1000

# Per-request timeout (0 = disabled)
TRANSLATE_TIMEOUT_SEC=180

# Retry-After estimation
RETRY_AFTER_MIN_SEC=1      # Floor
RETRY_AFTER_MAX_SEC=120    # Ceiling
RETRY_AFTER_ALPHA=0.2      # EMA smoothing factor
# Enable input filtering
INPUT_SANITIZE=1

# Minimum alphanumeric ratio (0.2 = 20%)
INPUT_MIN_ALNUM_RATIO=0.2

# Minimum character count
INPUT_MIN_CHARS=1

# Language code for undetermined/noise
UNDETERMINED_LANG_CODE=und
# Default sentence splitting behavior
PERFORM_SENTENCE_SPLITTING_DEFAULT=1

# Max chars per sentence before word-boundary split
MAX_SENTENCE_CHARS=500

# Max chars per chunk for batching
MAX_CHUNK_CHARS=900

# Sentence joiner
JOIN_SENTENCES_WITH=" "
# Enable symbol masking
SYMBOL_MASKING=1

# What to mask
MASK_DIGITS=1    # Mask 0-9
MASK_PUNCT=1     # Mask .,!? etc.
MASK_EMOJI=1     # Mask 😀🎉 etc.
# Align response array length to input
ALIGN_RESPONSES=1

# Placeholder for failed items (when aligned)
SANITIZE_PLACEHOLDER=""

# Response format
EASYNMT_RESPONSE_MODE=strings    # ["translation1", "translation2"]
EASYNMT_RESPONSE_MODE=objects    # [{"text":"translation1"}, ...]
# Enable two-hop translation via pivot
PIVOT_FALLBACK=1

# Pivot language (usually English)
PIVOT_LANG=en
# Log level
LOG_LEVEL=INFO

# Per-request logging (verbose)
REQUEST_LOG=1

# Format
LOG_FORMAT=plain    # Human-readable
LOG_FORMAT=json     # Structured JSON

# File logging with rotation
LOG_TO_FILE=1
LOG_FILE_PATH=/var/log/marian-translator/app.log
LOG_FILE_MAX_BYTES=10485760    # 10MB
LOG_FILE_BACKUP_COUNT=5

# Include raw text in logs (privacy risk!)
LOG_INCLUDE_TEXT=0
# Periodically clear CUDA cache (seconds, 0=disabled)
CUDA_CACHE_CLEAR_INTERVAL_SEC=0
# Worker count (use 1 for single GPU)
WEB_CONCURRENCY=1

# Request timeout
TIMEOUT=60

# Graceful shutdown timeout
GRACEFUL_TIMEOUT=20

# Keep-alive timeout
KEEP_ALIVE=5
# GET request
curl "http://localhost:8000/translate?target_lang=de&text=Hello%20world&source_lang=en"

# Response
{
  "translations": ["Hallo Welt"]
}
# POST request
curl -X POST http://localhost:8000/translate \
  -H 'Content-Type: application/json' \
  -d '{
    "text": [
      "Hello world",
      "This is a test",
      "Machine translation is amazing"
    ],
    "target_lang": "de",
    "source_lang": "en",
    "beam_size": 1,
    "perform_sentence_splitting": true
  }'

# Response
{
  "target_lang": "de",
  "source_lang": "en",
  "translated": [
    "Hallo Welt",
    "Das ist ein Test",
    "Maschinenübersetzung ist erstaunlich"
  ],
  "translation_time": 0.342
}
# Omit source_lang for auto-detection
curl -X POST http://localhost:8000/translate \
  -H 'Content-Type: application/json' \
  -d '{
    "text": ["Bonjour le monde"],
    "target_lang": "en"
  }'

# Response
{
  "target_lang": "en",
  "source_lang": "fr",  # Detected
  "translated": ["Hello world"],
  "translation_time": 0.156
}
# GET
curl "http://localhost:8000/language_detection?text=Hola%20mundo"
# {"language": "es"}

# POST with batch
curl -X POST http://localhost:8000/language_detection \
  -H 'Content-Type: application/json' \
  -d '{"text": ["Hello", "Bonjour", "Hola"]}'
# {"languages": ["en", "fr", "es"]}
# Health check
curl http://localhost:8000/healthz
# {"status": "ok"}

# Readiness
curl http://localhost:8000/readyz
# {
#   "status": "ready",
#   "device": "cuda:0",
#   "queue_enabled": true,
#   "max_inflight": 1
# }

# Cache status
curl http://localhost:8000/cache
# {
#   "capacity": 6,
#   "size": 3,
#   "keys": ["en->de", "de->en", "fr->en"],
#   "device": "cuda:0",
#   "inflight": 1,
#   "queue_enabled": true
# }

# Model info
curl http://localhost:8000/model_name | jq
# When queue is full, you get 429
curl -X POST http://localhost:8000/translate \
  -H 'Content-Type: application/json' \
  -d '{"text": ["test"], "target_lang": "de"}'

# Response: 429 Too Many Requests
# Headers: Retry-After: 45
# Body:
{
  "message": "Too many requests; queue full",
  "retry_after_sec": 45
}

# Proper client behavior:
# 1. Read Retry-After header
# 2. Wait that long + jitter
# 3. Retry request
٨-٨ آب/أغسطس
(أ) تقدير مرن يتكيف مع فترات الطلب الفعلية:
مثال:
.\build-all.ps1
ما الذي يحدث هنا؟
chmod +x build-all.sh
./build-all.sh
مثل متوسط مرجح يعطي أهمية أكبر للقيم الحديثةعامل المُسْس (ك):
latest, min, gpu, gpu-minلماذا ليس متوسطاً بسيطاً؟20250108.143022: يعطي زبائناً واقعيينالوقت الذي يتكيف مع نظام التحميل الحالي
# Always get the latest version
docker pull scottgal/mostlylucid-nmt:cpu
# Or use the :latest alias
docker pull scottgal/mostlylucid-nmt:latest

# Pin to a specific version for reproducibility
docker pull scottgal/mostlylucid-nmt:cpu-20250108.143022
docker pull scottgal/mostlylucid-nmt:cpu-min-20250108.143022
إدارة الموارد
: كش، تكسير، تكسير، وتجزئة، وتجهيز متوازي
docker inspect scottgal/mostlylucid-nmt:cpu | jq '.[0].Config.Labels'
: تفاصيل قطع الأشجار وتعقب القياسات.
# Using pre-built image from Docker Hub (recommended)
docker run -d \
  --name translator \
  -p 8000:8000 \
  -e ENABLE_QUEUE=1 \
  -e MAX_QUEUE_SIZE=500 \
  -e EASYNMT_BATCH_SIZE=16 \
  -e TIMEOUT=180 \
  -e LOG_LEVEL=INFO \
  -e REQUEST_LOG=0 \
  scottgal/mostlylucid-nmt

# Or build locally
docker build -t mostlylucid-nmt .
docker run -d --name translator -p 8000:8000 mostlylucid-nmt

# Check logs
docker logs -f translator
# Using pre-built GPU image from Docker Hub (recommended)
docker run -d \
  --name translator-gpu \
  --gpus all \
  -p 8000:8000 \
  -e USE_GPU=true \
  -e DEVICE=cuda:0 \
  -e PRELOAD_MODELS="en->de,de->en,en->fr,fr->en,en->es,es->en" \
  -e EASYNMT_MODEL_ARGS='{"torch_dtype":"fp16"}' \
  -e EASYNMT_BATCH_SIZE=64 \
  -e MAX_CACHED_MODELS=8 \
  -e ENABLE_QUEUE=1 \
  -e MAX_QUEUE_SIZE=2000 \
  -e WEB_CONCURRENCY=1 \
  -e TIMEOUT=180 \
  -e GRACEFUL_TIMEOUT=30 \
  -e LOG_FORMAT=json \
  -e LOG_TO_FILE=1 \
  -v /var/log/translator:/var/log/marian-translator \
  scottgal/mostlylucid-nmt:gpu

# Or build locally
docker build -f Dockerfile.gpu -t mostlylucid-nmt:gpu .
docker run -d --name translator-gpu --gpus all -p 8000:8000 mostlylucid-nmt:gpu

# Monitor cache and performance
watch -n 5 "curl -s http://localhost:8000/cache | jq"
version: '3.8'

services:
  translator:
    image: scottgal/mostlylucid-nmt:gpu  # Use pre-built image
    container_name: translator
    restart: unless-stopped

    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: 1
              capabilities: [gpu]

    ports:
      - "8000:8000"

    environment:
      USE_GPU: "true"
      DEVICE: "cuda:0"
      PRELOAD_MODELS: "en->de,de->en,en->fr,fr->en"
      EASYNMT_MODEL_ARGS: '{"torch_dtype":"fp16"}'
      EASYNMT_BATCH_SIZE: "64"
      MAX_CACHED_MODELS: "8"
      ENABLE_QUEUE: "1"
      MAX_QUEUE_SIZE: "2000"
      WEB_CONCURRENCY: "1"
      TIMEOUT: "180"
      LOG_FORMAT: "json"
      LOG_TO_FILE: "1"

    volumes:
      - translator-logs:/var/log/marian-translator
      - translator-cache:/root/.cache/huggingface

    healthcheck:
      test: ["CMD", "curl", "-f", "http://localhost:8000/healthz"]
      interval: 30s
      timeout: 10s
      retries: 3
      start_period: 40s

volumes:
  translator-logs:
  translator-cache:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: translator
spec:
  replicas: 2  # Scale horizontally for CPU, use 1 per GPU
  selector:
    matchLabels:
      app: translator
  template:
    metadata:
      labels:
        app: translator
    spec:
      containers:
      - name: translator
        image: scottgal/mostlylucid-nmt:gpu
        ports:
        - containerPort: 8000
        env:
        - name: USE_GPU
          value: "true"
        - name: EASYNMT_MODEL_ARGS
          value: '{"torch_dtype":"fp16"}'
        - name: PRELOAD_MODELS
          value: "en->de,de->en"
        - name: ENABLE_QUEUE
          value: "1"
        - name: MAX_QUEUE_SIZE
          value: "2000"

        resources:
          requests:
            memory: "4Gi"
            cpu: "2"
            nvidia.com/gpu: 1
          limits:
            memory: "8Gi"
            cpu: "4"
            nvidia.com/gpu: 1

        livenessProbe:
          httpGet:
            path: /healthz
            port: 8000
          initialDelaySeconds: 30
          periodSeconds: 10

        readinessProbe:
          httpGet:
            path: /readyz
            port: 8000
          initialDelaySeconds: 20
          periodSeconds: 5

---
apiVersion: v1
kind: Service
metadata:
  name: translator
spec:
  selector:
    app: translator
  ports:
  - port: 80
    targetPort: 8000
  type: LoadBalancer
مـدة مـا مـدة مـا مـدة مـدة مـدة مـا مـدة مـدة مـدة مـا
EASYNMT_MODEL_ARGS='{"torch_dtype":"fp16"}'
: جودة جيدة، 100 لغة، نموذج واحد، 2-2GB
# Start high, reduce if you get OOM
EASYNMT_BATCH_SIZE=64  # Try 128 on large GPUs
ال_مُعد__MUDEL_ FALBATO_MODEL
PRELOAD_MODELS="en->de,de->en,en->fr,fr->en,en->es,es->en"
: تجريب بصورة تلقائية عائلات أخرى إذا كانت غير متوفرة
WEB_CONCURRENCY=1
MAX_INFLIGHT_TRANSLATIONS=1
(يقصي): ممكن - أقصى تغطية
MAX_CACHED_MODELS=10 # Keep more models in VRAM
:: الإعاقة - وضع صارم لطريق الأسرة الواحدة
# beam_size=1 is 3-5x faster than beam_size=5
# Quality difference is often minimal
curl -X POST ... -d '{"beam_size": 1, ...}'
: ترتيب الأولوية للتراجع
EASYNMT_BATCH_SIZE=8
MAX_WORKERS_BACKEND=4
MAX_INFLIGHT_TRANSLATIONS=4
WEB_CONCURRENCY=2
)الأولوية(
PERFORM_SENTENCE_SPLITTING_DEFAULT=0
)الشرعة الأولى(
// Bad: 100 separate requests
for (const text of texts) {
  await translate(text);
}

// Good: 1 batch request
await translate(texts);
زمــود الزمــود _ الكاكــاي/الضــيــر
async function translateWithRetry(texts) {
  try {
    return await translate(texts);
  } catch (err) {
    if (err.status === 429) {
      const retryAfter = err.headers['retry-after'];
      const jitter = Math.random() * 5;
      await sleep((retryAfter + jitter) * 1000);
      return translateWithRetry(texts);
    }
    throw err;
  }
}
: تخزين النموذج الثابت عن طريق أحجام
// Reuse HTTP connections
const agent = new https.Agent({ keepAlive: true });
// Bad: mixed language pairs in one request
translate([
  { text: "Hello", sourceLang: "en", targetLang: "de" },
  { text: "Bonjour", sourceLang: "fr", targetLang: "de" }
]);

// Good: group by language pair
translateBatch(enToDe, "en", "de");
translateBatch(frToDe, "fr", "de");
أمثلة
translation_requests_total{lang_pair="en->de",status="success"} 1523
translation_requests_total{lang_pair="en->de",status="error"} 7
translation_duration_seconds{lang_pair="en->de",quantile="0.5"} 0.342
translation_duration_seconds{lang_pair="en->de",quantile="0.95"} 1.234
translation_queue_depth 23
translation_cache_size 6
translation_cache_hits_total 8234
translation_cache_misses_total 142
# Enable JSON logging
LOG_FORMAT=json REQUEST_LOG=1

# Output example
{
  "ts": "2025-01-08T15:30:45+0000",
  "level": "INFO",
  "name": "app",
  "message": "translate_post done items=5 dt=0.342s",
  "req_id": "a3d2f5b1-c4e6-4f7a-9d8c-1e2f3a4b5c6d",
  "endpoint": "/translate",
  "src": "en",
  "tgt": "de",
  "items": 5,
  "duration_ms": 342
}
تمت إعادة التوصية (معاد التوصية)
المصدر فقط |---------|---------|-----------------| | نقاط النهايةدال)أ( | **المحتويات (تابع)**وتشمل جميع صور Dooker الآن الإصدارات الصحيحة والبيانات الفوقية للتتبع. | إنشاءQQQQQQبناء الكل مع تلقائي التاريخ الوقت: | ****لين لين/ ما ماك: | أولاً - مقدمـة فـيبناء بناء | مُزث | - يشير دائماً إلى أحدث | (مثلاً، مثلاً،- لمحة غير دقيقة | **أمثلة:**OCI Alels | تشمل كل صورة ما يلي: | بناء الوقت (YYYYMYD.HMMMS)& حد الإنشاء | ISO: ISO 8601 مزامن: ISO 8601يُغغِّي في الالتزام
: ctpu-ful, cpu-min, gpu-ful, gpu-min:::::::
وللاطلاع على تعليمات تفصيلية بشأن البناء والاندماج في مركز التنسيق المشترك بين الوكالات، انظر الوثيقة A/CI/CD.
MAX_QUEUE_SIZEMAX_INFLIGHT_TRANSLATIONSالوزعالأداءGPUGP
ENABLE_QUEUE=1حجم الدفعةنماذج حارات ما قبل ما قبل التحميل
كل عامل منفرد لكل وحدة
EASYNMT_BATCH_SIZEMAX_CACHED_MODELSEASYNMT_MODEL_ARGS='{"torch_dtype":"fp16"}'WEB_CONCURRENCY=1الزيادة في الموازيةMAX_INFLIGHT_TRANSLATIONS=1أفضل الممارساتطلبات تقديم الطلبات
PRELOAD_MODELS="en->de,de->en"
المجموعة حسب اللغة Helsinki-NLP/opus-mt-{src}-{tgt}الرصد والملاحظة
& رئيسية إلى المقطوعة
PIVOT_FALLBACK=1(الطلبات/الطلبات)curl http://localhost:8000/lang_pairsالعمق(عدد الانتظار الحالي)
معدل المضرب
MASK_EMOJI=0معدلMASK_PUNCT=0SYMBOL_MASKING=0(كذلك ما فُككُلُ
public class MostlyLucidNmtClient
{
    private readonly HttpClient _httpClient;
    private readonly string _baseUrl;

    public MostlyLucidNmtClient(HttpClient httpClient, string baseUrl)
    {
        _httpClient = httpClient;
        _baseUrl = baseUrl;
    }

    public async Task<TranslationResponse> TranslateAsync(
        List<string> texts,
        string targetLang,
        string sourceLang = "",
        int beamSize = 1,
        bool performSentenceSplitting = true,
        CancellationToken cancellationToken = default)
    {
        var request = new TranslationRequest
        {
            Text = texts,
            TargetLang = targetLang,
            SourceLang = sourceLang,
            BeamSize = beamSize,
            PerformSentenceSplitting = performSentenceSplitting
        };

        var response = await _httpClient.PostAsJsonAsync(
            $"{_baseUrl}/translate",
            request,
            cancellationToken);

        if (response.StatusCode == System.Net.HttpStatusCode.TooManyRequests)
        {
            // Read Retry-After header
            var retryAfter = response.Headers.RetryAfter?.Delta?.TotalSeconds ?? 30;
            var jitter = Random.Shared.Next(0, 5);
            await Task.Delay(TimeSpan.FromSeconds(retryAfter + jitter), cancellationToken);

            // Retry
            return await TranslateAsync(texts, targetLang, sourceLang, beamSize,
                performSentenceSplitting, cancellationToken);
        }

        response.EnsureSuccessStatusCode();
        return await response.Content.ReadFromJsonAsync<TranslationResponse>(cancellationToken);
    }
}

public class TranslationRequest
{
    [JsonPropertyName("text")]
    public List<string> Text { get; set; }

    [JsonPropertyName("target_lang")]
    public string TargetLang { get; set; }

    [JsonPropertyName("source_lang")]
    public string SourceLang { get; set; }

    [JsonPropertyName("beam_size")]
    public int BeamSize { get; set; }

    [JsonPropertyName("perform_sentence_splitting")]
    public bool PerformSentenceSplitting { get; set; }
}

public class TranslationResponse
{
    [JsonPropertyName("target_lang")]
    public string TargetLang { get; set; }

    [JsonPropertyName("source_lang")]
    public string SourceLang { get; set; }

    [JsonPropertyName("translated")]
    public List<string> Translated { get; set; }

    [JsonPropertyName("translation_time")]
    public double TranslationTime { get; set; }
}
التذكر
services.AddHttpClient<MostlyLucidNmtClient>(client =>
{
    client.BaseAddress = new Uri("http://translator:8000");
    client.Timeout = TimeSpan.FromMinutes(3);
});
مُنْ مِنْ مِنْ مِنْ مِنْإذا دمجت بروميثيوس (ليس مدمجاً فيه، ولكن من السهل إضافته):
(أ) مقارنة: WeilNMT vs miss miss lis Llousid-NMT
□ دليل، لا يوجد مخبأ لـ LRU مع Auto- viviction
-
Limited Limited Limited o 40+ env pars لضبط الضبطمدى التوافق في
# Maximum coverage with auto-fallback (recommended!)
docker run -d -p 8000:8000 \
  -v ./model-cache:/models \
  -e MODEL_CACHE_DIR=/models \
  -e AUTO_MODEL_FALLBACK=1 \
  -e MODEL_FALLBACK_ORDER="opus-mt,mbart50,m2m100" \
  scottgal/mostlylucid-nmt:cpu-min

# GPU with best quality
docker run -d --gpus all -p 8000:8000 \
  -e USE_GPU=true \
  -e MODEL_FAMILY=opus-mt \
  -e EASYNMT_MODEL_ARGS='{"torch_dtype":"fp16"}' \
  scottgal/mostlylucid-nmt:gpu

# Test it
curl -X POST http://localhost:8000/translate \
  -H 'Content-Type: application/json' \
  -d '{"text": ["Hello world"], "target_lang": "de"}'
OOOM (من الذاكرة) على GPU
السبب:
حجم الخزائن عالي جداً أو الكثير جداً من النماذج المخبأة.
طلب أول بطيئة بطيئة[السبب:
Translation NMT Neural Machine Translation Python FastAPI Docker CUDA PyTorch Transformers Helsinki-NLP Production Microservices API

© 2026 Scott Galloway — Unlicense — All content and source code on this site is free to use, copy, modify, and sell.
